
TL;DR

Get business pricing on monitors, keyboards and dev gear
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
The latest Sentence Transformers update introduces MultiVectorEncoder, supporting end-to-end training of ColBERT-style retrieval models. A medical retrieval model outperformed general-purpose systems in initial tests, but independent validation is pending. This development could enhance domain-specific search applications.
Sentence Transformers v6.0 has introduced MultiVectorEncoder, a new model type supporting ColBERT-style late interaction retrieval within its Python library. The update includes an end-to-end training workflow that allows developers to fine-tune or build domain-specific retrieval models more easily, with initial tests showing promising results in medical search applications. For a detailed overview, see the original analysis on training and finetuning multi-vector embedding models.
The new MultiVectorEncoder expands Sentence Transformers beyond dense embeddings, enabling models that retain separate token vectors for late-interaction scoring. This approach, based on the ColBERT architecture, compares query and document tokens using a MaxSim operation, which can preserve phrase-level signals often lost in single-vector representations. The release provides a comprehensive training pipeline, including datasets, loss functions, training arguments, evaluators, and trainers, all accessible via a simple package command (pip install -U ‘sentence-transformers[train]’). For more insights, see the original analysis on training and finetuning multi-vector embedding models.
The author of the update trained a medical retrieval model for 14.5 hours on an Nvidia RTX 3090, reporting that it outperformed all other general-purpose dense, sparse, and multi-vector models tested on a medical dataset. However, this result remains an initial experiment and has not been independently verified. The new model type supports long documents, addressing a common limitation where traditional models truncate passages at 180–300 tokens, which can negatively impact retrieval quality, especially in specialized fields like medicine where passages often exceed 900 tokens.
Implications for Domain-Specific Retrieval Models
This development offers a more accessible pathway for organizations to develop domain-specific retrieval systems without building complex training stacks from scratch. By supporting late-interaction models like ColBERT, Sentence Transformers can now better handle specialized vocabularies and longer documents, which are common in fields such as healthcare, law, and scientific research. If validated through further testing, these models could significantly improve search relevance and accuracy in these sectors, where generic web-search models often fall short.
Products Worth Considering

Samsung 27-inch Odyssey OLED G6 QD-OLED QHD Gaming Monitor

Anker SOLIX S2000 Portable Power Station, 2,010Wh, 1,500W
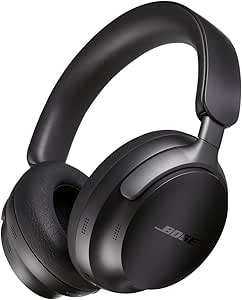
Bose QuietComfort Ultra Wireless Noise-Cancelling Headphones with Spatial Audio, Black
As an affiliate, we earn on qualifying purchases.
Evolution of Retrieval Architectures in Sentence Transformers
Prior to v6.0, Sentence Transformers primarily supported workflows based on dense embeddings, sparse embeddings, and rerankers. The introduction of MultiVectorEncoder marks the addition of a native training capability for ColBERT-style late interaction retrieval, a method that maintains separate token vectors for queries and documents, enabling more nuanced similarity scoring. The approach was inspired by earlier domain-specific retrieval needs, such as LightOn’s development of LateOn-Code for code search, which highlighted the limitations of general models in specialized contexts.
The update also emphasizes the importance of matching input length to real document sizes, as longer passages—common in medical literature—can suffer from truncation in traditional models, leading to decreased relevance scores. The new workflow simplifies the process of training models tailored to these longer documents, potentially improving retrieval performance in practical applications.
“The v6.0 update introduces a new MultiVectorEncoder for ColBERT-style retrieval, along with a complete training workflow that makes domain-specific models more accessible.”
— Thorsten Meyer, author of the update
Unverified Performance Gains and Benchmark Limitations
It is not yet clear how well the reported medical retrieval improvements will generalize to other datasets or domains, as the benchmark details are limited. The comparison lacks full disclosure of dataset construction, tuning procedures, and statistical significance. Additionally, the operational costs—such as storage, indexing time, and query latency—have not been quantified, leaving questions about practical deployment unanswered. Independent reproduction and validation are still pending.
Expected Steps for Validation and Broader Adoption
Developers and researchers are encouraged to install Sentence Transformers v6.0, select existing multi-vector checkpoints, and test the training workflow with their domain data. Future work will focus on reproducing the initial medical results across diverse datasets, measuring performance, cost, and scalability. Independent benchmarks and real-world case studies will be crucial to confirm the model’s advantages and limitations, guiding broader adoption in specialized search applications.
Key Questions
How does MultiVectorEncoder differ from previous models?
MultiVectorEncoder supports late-interaction retrieval, maintaining separate token vectors for queries and documents, unlike dense models that compress entire texts into single vectors. This allows for finer-grained similarity scoring, especially beneficial for long documents and domain-specific vocabularies.
Can I train my own domain-specific retrieval model using this update?
Yes. The update provides a complete training workflow, enabling users to fine-tune existing checkpoints or build new models from base transformers using their domain data, such as medical or legal texts.
What are the limitations of the current results?
The reported improvements are based on initial experiments with limited datasets, without independent validation. Practical costs like storage and latency are also not fully quantified, so real-world performance remains to be confirmed.
Will this approach work for very long documents?
Yes. The new model supports longer documents, addressing a key limitation of traditional models that truncate passages at 180–300 tokens. Longer inputs can improve retrieval relevance in fields like medicine, where passages often exceed 900 tokens.
Source: ThorstenMeyerAI.com