🔍 Read the full analysis: What Makes NVIDIA Kumo Tabular’s Prediction Approach Different? on ThorstenMeyerAI.com

Get business pricing on monitors, keyboards and dev gear
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
TL;DR
NVIDIA has released Kumo Tabular, an open model for classification and regression that uses labeled rows as context to predict labels for new rows without task-specific training or tuning. NVIDIA says it ranks first on four benchmarks, but the supplied release material does not provide scores, detailed comparisons or independent validation.
NVIDIA has released Kumo Tabular, an open model for classification and regression that predicts outcomes for new table rows from labeled examples, without updating its weights for each task. The company says the model ranks first on four benchmarks, but the supplied release material does not include benchmark scores or independent checks, leaving its comparative performance on business data unverified.
Kumo Tabular is part of NVIDIA’s Kumo Structured model collection. A user provides rows with known labels alongside rows that need predictions. The model returns class probabilities for classification or numeric estimates for regression. NVIDIA describes this as a single-forward-pass workflow that avoids task-specific training, tuning and feature engineering.
The release includes three model sizes, from 28 million to 215 million parameters. NVIDIA says the weights are available on Hugging Face and the code through GitHub, with use supported by an open-source library. The stated OpenMDW-1.1 license permits commercial use, according to the company; organizations still need to review the license and suitability for their own applications.
NVIDIA says Kumo Tabular ranks first on TabArena, BeyondArena, TALENT and ScoringBench. Those rankings are company claims in the supplied material. It does not provide scores, evaluation settings, named competing models or independent validation, so the claims do not establish how the model would compare on a particular organization’s data.
A Different Workflow for Table Prediction
Many business prediction tasks rely on structured records, including transactions, customer accounts, insurance claims and sensor readings. Common practice is to prepare a dataset, select and train a model, engineer features and tune settings for each task. Kumo Tabular proposes a different entry point: give a pretrained model labeled examples in a table and ask it to predict the labels for other rows.
If it works well for a given task, that approach could reduce the time and technical effort required to test a prediction idea, particularly when teams have labeled data but limited modeling resources. The release does not show that it replaces established production methods. Businesses would need to test it against current approaches on held-out data, considering accuracy, latency, resource use and reliability as well as the ease of setup.
That distinction matters because a faster initial workflow is not necessarily a better production system. A model that performs well on a benchmark may behave differently on data with unusual categories, severe class imbalance or patterns absent from its pretraining. For readers evaluating the announcement, the practical question is not only whether task-specific training can be skipped, but whether the predictions are good enough—and economical enough—for a specific use.
Products Worth Considering
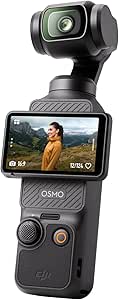
DJI Osmo Pocket 3 Vlogging Camera with 1-Inch CMOS Sensor and 4K Video

Sony WH-1000XM6 Wireless Noise-Canceling Over-Ear Headphones, Blue, Bundle

Bose QuietComfort Wireless Bluetooth Headphones with Active Noise Cancellation, Mic, USB‑C Charging, Deep Bass, 24‑Hour Battery – White Smok
As an affiliate, we earn on qualifying purchases.
Synthetic Pretraining and In-Context Learning
Kumo Tabular is a Transformer designed for tables, using column, row and in-context attention, according to NVIDIA. The company says it was pretrained entirely on artificially generated tables, created by sampling structural causal models with varied relationships and data types. The generated data includes imperfections such as missing values; the release also describes correlated features and outliers as part of the generation process.
At prediction time, labeled examples serve as context. The model’s weights are not updated for each new task, distinguishing the approach from a conventional workflow that trains or tunes a separate model on task-specific data. NVIDIA says the design draws on methods introduced in TabICL and TabPFN. Its description says a tree-ensemble check filters generated tables that lack a learnable signal.
The source material does not state the total volume of synthetic pretraining data or detail how closely those generated tables reflect the range of real organizational datasets. That leaves an important gap between the model’s proposed general-purpose design and evidence about performance on specific, messy business records.
““Given a table of labeled rows, it predicts the labels of new rows in a single forward pass, with no training, no tuning, and no feature engineering.””
— NVIDIA, in the supplied Hugging Face release
Benchmark Evidence Still Missing
The supplied announcement does not include benchmark scores, baselines, evaluation dates or independent checks for the four rankings. It is not clear how the model compares with tuned tree-based systems on the same datasets or how results vary with table size, class imbalance, high-cardinality categories and extensive missing data.
NVIDIA describes regression predictions as including uncertainty estimates through predicted quantiles, but the material provides no results on how well those estimates are calibrated. It also gives no detailed figures for inference costs, latency, compute requirements or deployment limits. Those details affect whether the model is practical beyond a demonstration.
More broadly, the source does not establish that synthetic pretraining covers the patterns found in any particular organization’s data. Real-world accuracy and operating costs remain unconfirmed, as does the extent to which the model’s simpler setup translates into an advantage over existing methods.
Independent Tests Will Matter
With the weights and code available, practitioners can evaluate Kumo Tabular on their own tasks. A useful comparison would use held-out data and the organization’s existing method, reporting task-specific accuracy measures alongside inference speed and resource use. Teams considering consequential applications would also need to examine prediction uncertainty and failure cases before relying on the output.
The next evidence to watch for is detailed benchmark reporting and independent comparisons that identify datasets, baselines and test conditions. Until that evidence is available, NVIDIA’s rankings are best treated as claims from the release, not as proof that Kumo Tabular will outperform alternatives in production.
Key Questions
What is NVIDIA Kumo Tabular?
It is an open model for classification and regression on structured tables. It uses labeled rows as context to predict outcomes for other rows.
Does it train a new model for every task?
NVIDIA says no. The model uses examples provided at prediction time and does not update its weights for each task. The company describes the process as requiring no task-specific training, tuning or feature engineering.
How strong are its benchmark results?
NVIDIA says Kumo Tabular ranks first on TabArena, BeyondArena, TALENT and ScoringBench. The supplied material does not provide scores, detailed baselines or independent validation, so the rankings cannot establish how it will perform on a reader’s own data.
Can businesses use Kumo Tabular commercially?
NVIDIA says the model uses the OpenMDW-1.1 license, which permits commercial use. Organizations should review the license terms and assess the model’s behavior and requirements for their intended application.
What should an organization test before adopting it?
Compare predictions with current methods on held-out, task-relevant data. Measure accuracy, speed, compute costs and uncertainty quality, and check behavior on missing values, imbalanced classes and unusual categories.
Primary source: Hugging Face · via ThorstenMeyerAI.com