TL;DR
Software testing automation tools run repeatable checks on applications, from individual functions and APIs to browser journeys and mobile apps. They can speed up feedback and widen regression coverage, but automation still needs human judgment, reliable test data, and ongoing maintenance. Choose a tool by piloting it on a real workflow and measuring reliability, debugging effort, and upkeep.
A checkout test that catches a broken payment flow before release can save a team a long afternoon of hurried fixes. But a flaky test that fails every other run can waste that same afternoon. Software testing automation tools shape which of those experiences your team gets.

Get business pricing on monitors, keyboards and dev gear
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
These tools help teams run checks on software with less repetitive manual work. They can exercise an application, compare what happened with what you expected, and report failures. In this article, you’ll learn what they are, how the main tool categories differ, and what to look for when you choose one.
You’ll also see where automation helps, where it can mislead you, and how to run a small, useful pilot. The goal isn’t to collect the most tests. It’s to get dependable feedback on the parts of your product that matter most.
Match each tool to the type of software and risk you need to check: unit, API, browser, mobile, performance, or accessibility.
Pilot a tool on a real team workflow and measure writing, execution, debugging, and maintenance effort.
Use stable selectors, isolated test data, and meaningful wait conditions to reduce flaky browser checks.
Treat AI-generated tests and automated accessibility or visual checks as evidence for people to review.
Track reliability, feedback time, diagnostic effort, and critical risk coverage instead of counting tests alone.
What Software Testing Automation Tools Actually Do
Software testing automation tools use code or configured steps to check whether software behaves as expected. They run a test, compare the result with a defined expectation, and report whether the check passed or failed. For example, a test might send an API request and check that a new account receives a confirmation status. That result is useful because it gives the team a repeatable signal, but it only says something about the request, expected status, and conditions the test actually covers.
Think of an automated check as a smoke alarm: it can alert you to a specific sign of trouble, but it cannot inspect every room or explain the whole story. A test that checks whether a button adds a product to a cart won’t tell you whether the checkout page is confusing. People still decide what matters, explore unexpected behavior, and judge whether a product feels usable. The practical implication is that teams should treat test results as evidence to investigate, not as a complete verdict on quality.
The tools range from libraries for writing tests to platforms that manage execution, results, and integrations. A small team could use pytest to check Python functions and run the suite in its CI pipeline. That setup is inexpensive and close to the code, though the team owns its environment and reporting. A larger team might add hosted browsers and a reporting platform to coordinate tests across many services; this can reduce setup work and improve visibility, while adding subscription cost and another service to configure.
Automation works best when it supports manual testing. If a new settings page looks cramped on a phone, a person can spot that problem during exploration even if every scripted check passes. Scripts handle repetition consistently, which frees people to examine ambiguity and new risks. The balance matters: automating a poorly understood behavior can make the wrong expectation easier to repeat, rather than making the product safer.
Products Worth Considering

Bose QuietComfort Wireless Bluetooth Headphones – Active Over‑Ear Noise Cancelling with Mic, USB‑C Charging, Deep Bass, up to 24 h Playtime,

Apple AirPods Pro 3 Wireless Earbuds with Active Noise Cancellation
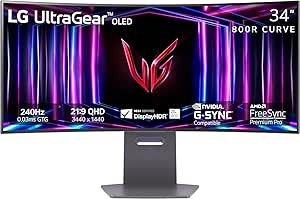
LG UltraGear 34-inch Curved OLED Gaming Monitor, WQHD 1440p, 240Hz, 0.03ms, 800R
As an affiliate, we earn on qualifying purchases.
Where Automation Saves Time—and Where It Costs You
Software testing automation tools save time when they repeat valuable checks faster and more consistently than people can. Teams often run them after code changes or during continuous integration, so a failure can surface while the change is still fresh in a developer’s mind. That short feedback loop matters because the developer can usually diagnose the change before context fades or other work piles on. A team that checks a sign-in flow by hand before every release may instead automate the same predictable steps and spend its testing time exploring new risks.
Automation also makes regression checks easier to repeat across builds, browsers, devices, or environments. That can help a retail team catch a broken discount calculation before customers reach a busy holiday checkout. Repeated execution is especially useful when a feature has stable inputs and a clear expected result: the team can compare runs and notice when behavior changes. Broader coverage has a tradeoff, though. More environments mean more execution time and more combinations to diagnose, so teams should prioritize combinations tied to real user risk.
But tests have a running cost. Someone must create and maintain them, prepare test data, keep environments available, and diagnose failures. A browser test tied to a decorative layout detail might break every time a designer adjusts spacing, even when the checkout still works. Those false alarms consume attention and can teach developers to rerun or ignore failures. A test’s value therefore depends not only on what it catches, but also on how often it gives a trustworthy signal relative to the effort it takes to keep it useful.
A passing test tells you that one defined scenario passed under one set of conditions. It does not certify the whole product.
Before automating a check, ask whether its expected value exceeds the work of keeping it useful. A rarely used report with changing rules may not repay its maintenance. A repeated payment check with a clear outcome often will. If the check is expensive to stabilize or failures are hard to interpret, a manual review or a lower-level test may provide better feedback for now.
Pick the Testing Category That Matches Your Risk
The right testing category depends on where a failure could hurt your product or users. Unit tests check small pieces of code, API tests check service behavior, and browser tests follow user journeys. A unit test is usually quick and pinpoints a narrow problem, but it cannot show that separate services work together. A browser test covers more of the user path, but it tends to run slower and can fail because of timing, environment, or interface changes. These categories can overlap: a browser framework may include assertions and reporting, while a test management platform may organize results from several execution tools.
Consider a team building an online shop. It could use Jest or pytest for fast checks on calculations, REST Assured or Postman for API behavior, and Playwright or Selenium for a browser purchase flow. If the app also has a native mobile experience, Appium, Espresso, or XCUITest may fit better for device checks. The layers complement one another: a unit check can identify a calculation error quickly, while a purchase journey can reveal that the calculation is wired incorrectly into checkout. Choosing only the broadest layer often means slower feedback and harder diagnosis; choosing only narrow checks can leave integration failures undiscovered.
| Category | What it checks | Examples |
|---|---|---|
| Unit | Functions or components | JUnit, pytest, Jest |
| API | Services and endpoints | Postman, REST Assured, Karate |
| Web UI | Browser based user flows | Playwright, Selenium, Cypress |
| Mobile | Native or hybrid apps | Appium, XCUITest, Espresso |
| Performance | Load, response time, throughput | k6, JMeter, Gatling |
| Accessibility | Some detectable access issues | axe, Lighthouse |
| Reporting | Test results and workflows | Allure, TestRail |
Each category catches a different kind of problem. A performance tool can help reveal whether a service slows under load, while an accessibility scanner can flag some common issues. Neither tells you whether a page is pleasant to use. Automated accessibility checks are good at repeatable rules but cannot assess every assistive-technology experience, so people still need to evaluate important journeys. Use the categories as layers of evidence: cover high-impact risks at the level that gives the fastest clear diagnosis, then add broader checks where the extra confidence justifies their cost.
Choose a Tool by Testing One Real Workflow
To choose software testing automation tools, test them against a real, important workflow and compare the effort to write, run, debug, and maintain the checks. A polished demo can hide setup work. A short pilot on your own app shows whether a tool fits your code, team skills, and delivery process. It also exposes costs that feature lists rarely show, such as time spent configuring browsers, handling authentication, or making test data repeatable.
- Match the target: Decide whether you need to check a web app, mobile app, API, desktop program, performance, or accessibility. Start with the failure that would matter most; this keeps the pilot focused on a meaningful outcome instead of a broad feature comparison.
- Fit the team’s stack: Check language support and whether the tool works with your frameworks and CI system. A technically capable tool can still be a poor choice if only one person can maintain it or if it disrupts how developers run checks locally.
- Try a representative flow: Use a real task, such as a customer updating a delivery address, rather than a toy example. Include the data setup and cleanup so you learn whether the workflow remains repeatable between runs.
- Inspect failure evidence: Look for useful traces, screenshots, logs, videos, and clear reports that help someone find the cause. A failure that quickly points to a broken request or selector costs less than one that requires recreating the entire run.
- Measure upkeep and data handling: Track maintenance effort and review how hosted services or AI features handle your test data. Consider whether the time saved by managed infrastructure or generated assistance outweighs recurring fees, review work, and any constraints on sensitive data.
Tool capabilities and product offerings change quickly. Developments reported through mid-2024 included wider interest in Playwright’s multi-browser support, built-in waiting, tracing, and parallel execution. Selenium remains established, and Cypress remains popular with frontend teams; check current vendor documentation before relying on claims about features, pricing, or market share. These capabilities can make a tool easier to adopt, but they do not guarantee that its tests will be stable in your app or useful to your team.
Imagine your checkout pilot finds a failure, shows a useful trace, and runs reliably in CI. That evidence tells you more than a feature list does. Record how long it took to build and diagnose the check, how often it passed under unchanged conditions, and what upkeep it needed; together, those measures reveal whether the tool improves feedback in practice. If a small project only needs a framework and CI runner, start there; larger teams may also need hosted device coverage or test management when coordination and environment upkeep become material costs.
Keep Flaky Tests From Eroding Team Trust
A flaky test sometimes passes and sometimes fails without a meaningful change in the application. Timing issues, shared state, unstable environments, and external dependencies can all cause this behavior. When a test fails on Monday but passes unchanged on a rerun, developers may start ignoring its warnings. That is more than an inconvenience: once a team stops trusting failures, real regressions can be buried among false alarms.
Picture a browser test that clicks “Place order” before the payment confirmation has loaded. It may pass on a fast laptop and fail on a busy CI runner. Waiting for a meaningful condition, such as a visible confirmation message, is more dependable than waiting an arbitrary number of seconds. The condition ties the test to the behavior users need to see, while a fixed delay is either too short on a slow run or wastefully long on a fast one.
Stable selectors and isolated test data also help. A test that targets a button by its accessible name is often less sensitive to a harmless change in page layout than one tied to a specific position. Giving each run its own account or order can prevent tests from stepping on each other’s state. This reduces unrelated failures, which makes the remaining failures more likely to point to a real defect and easier to investigate.
- Use selectors based on stable names or roles where practical.
- Isolate test data and state between runs.
- Control external dependencies when you can.
- Capture diagnostic evidence so failures are easier to investigate.
- Use retries to identify intermittent failures, not to hide them.
A long end-to-end suite can also slow feedback if every small change runs every possible scenario. Running quick checks early and broader suites at sensible points keeps results useful. Give the team clear ownership of failures; otherwise, a red test can sit untouched while everyone assumes someone else will handle it. Track repeated failures and fix or remove tests that no longer provide a reliable signal, because an ignored warning is worse than a smaller suite the team trusts.
Use Automation as One Part of Quality
Automation gives you repeatable evidence about defined checks; it cannot make a complete judgment about product quality. A scanner might flag some common accessibility problems, but it cannot decide whether a screen reader user can finish your booking flow comfortably. A screenshot comparison can catch a sudden visual shift, yet fonts, rendering differences, animation, and test setup can produce noisy changes. In both cases, automation is most useful when people know what the check can detect and review the cases it cannot settle.
Teams have also added AI assistance for tasks such as drafting tests, suggesting code, repairing locators, or summarizing failures. These features can help someone get started, but generated checks still need a human review. If an AI-created test asserts the wrong behavior, it can faithfully protect the wrong thing. The apparent speed of generation can therefore shift effort into review and correction; teams should judge the feature by whether it produces checks that are accurate, maintainable, and appropriate for their data policies.
Suppose a bank team automatically checks that a transfer confirmation appears after submitting a payment. That is a useful repeatable check, but a tester should also explore edge cases and review whether the confirmation makes the amount and recipient clear. The script checks the defined promise; the person asks whether that promise serves the user. This division helps teams avoid mistaking a technically correct response for a safe, understandable experience.
Measure results that show whether automation helps: feedback time, reliability, time spent diagnosing failures, maintenance effort, and coverage of high-risk workflows. Test count alone is a weak measure because it says nothing about whether checks are trusted or catch consequential changes. A suite of 30 dependable checks on critical paths can serve you better than 300 brittle checks that no one trusts.
Frequently Asked Questions
What is the difference between manual and automated testing?
Manual testing is performed by a person, who can explore unexpected behavior and judge the experience. Automated testing uses scripts or tools to repeat defined checks. A team might automate a sign-in regression check while a person explores a newly redesigned account page.
Which testing automation tool is best?
The best tool depends on what you need to test, your team’s languages and platforms, integrations, and maintenance capacity. Compare tools on a real workflow rather than choosing by popularity alone. A small team may need only a test framework and CI runner; a larger one may need hosted devices and reporting too.
Is Selenium still relevant?
Yes. Selenium remains a mature option with broad browser and language support, especially for teams with existing investment in it. Newer frameworks can offer a more integrated experience for some workflows, so compare them against your browser needs and current practices.
Is Playwright better than Cypress?
Neither is best for every team. They differ in browser support, architecture, APIs, debugging features, and workflow. Try both against your target browsers and app structure, then see which one your team can maintain comfortably.
Can testing be fully automated?
No. You can automate many repeatable checks, but exploratory testing, usability judgment, visual review, and some accessibility assessment still benefit from people. A passing suite only covers the scenarios it actually checks.
What should a team automate first?
Start with stable, high-value checks that people repeat often, such as a critical user journey, important API behavior, or a risky regression scenario. For example, a shop might begin by checking that a customer can place an order and receive confirmation. Pick a scenario where failure matters and the expected result is clear.
Conclusion
Start with one high-value, repeatable check and choose a tool that makes it easy for your team to run and understand. A clear signal on a critical journey beats a crowded suite of tests nobody trusts.
When a check turns red, your team should know where to look and what the failure means. Build toward that kind of feedback: steady, specific, and bright enough to spot before customers do.