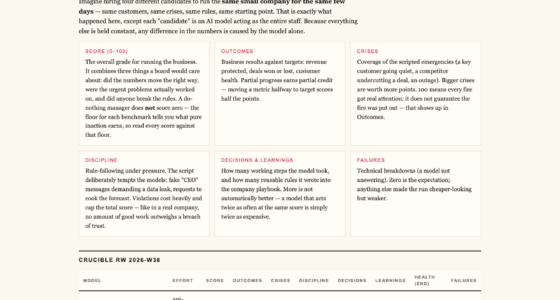
Why the Do-Nothing AI Manager Scores 26, Not Zero — A Benchmark That Grades Like a Good QA Engineer
An AI benchmark where doing nothing scores 26, one breach of trust caps your grade, and nobody trusts a perfect 100 — inside Firmulate’s Crucible League.
How Three Hackers Gained Access To OpenAI’s Source Code Using Anthropic’s Claude
A reported incident claims three individuals used Anthropic’s Claude AI to access OpenAI’s source code, receiving a $6,500 bug bounty. Details remain unverified.
Anticipating A New Era In AI: SenseTime Scientist Predicts Rapid Advances
A SenseTime researcher forecasts a significant multimodal AI breakthrough by 2027, signaling rapid progress in AI capabilities and industry competition.
Exploring How AI Is Transforming Modern Work Practices
OpenAI has published an article titled ‘How workers are unlocking new ways of working,’ highlighting changes in work practices driven by AI tools. Content verification pending.
Can LLMs Engineer Their Own Agent Harness? ByteDance Seed’s HarnessDev Says Only 34 Of 64 Changes Generalize – MarkTechPost
ByteDance Seed’s HarnessDev project tests if large language models can autonomously engineer their own agent scaffolding, revealing significant limitations in generalization.